I want to use heterogeneity and relationships in my application to create different views on my data.
Lets say I have the following objects:
- Folders
- Items
and the following rules apply:
- A Folder can contain (sub)folders or items.
- An Item must be in a Folder
Is there any advice on getting the best performance out of my application?
At the moment I’m modeling the data graph so that I can create the UI views that I want. I want to be able to:
- View all Folders and Items in an Overview
- View all Folders and Items in a Tree
This has led to the following model graph
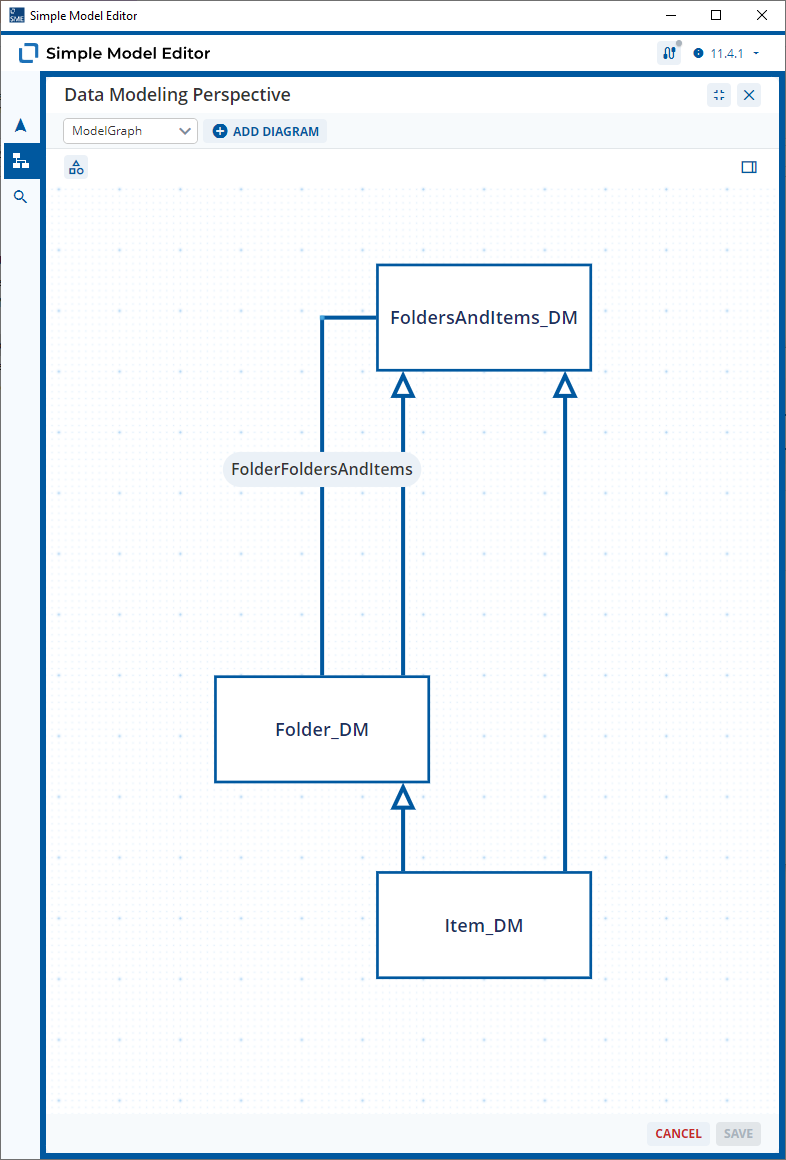
However, I’m concerned that when I load the Tree that the performance will suffer as:
- I load the Folders at root level
- I load the linked Folders and Items
- To load the linked Folders and Items I need to search the two subtypes, Folder_DM and Item_DM
- Item_DM is a subtype of Folder_DM so could be loaded / searched twice
Is this all taken care of for me through Heterogeneity Resolution in Data Services or do I need to change my modeling?